The answer is in a video. Your search box is looking for a paragraph.
That gap shows up everywhere: a repair recorded on someone’s phone, a diagram buried in a slide deck, an explanation left as a voice note. Your team has the knowledge. Finding it still depends on remembering the filename, the right keyword, or the person who made it.
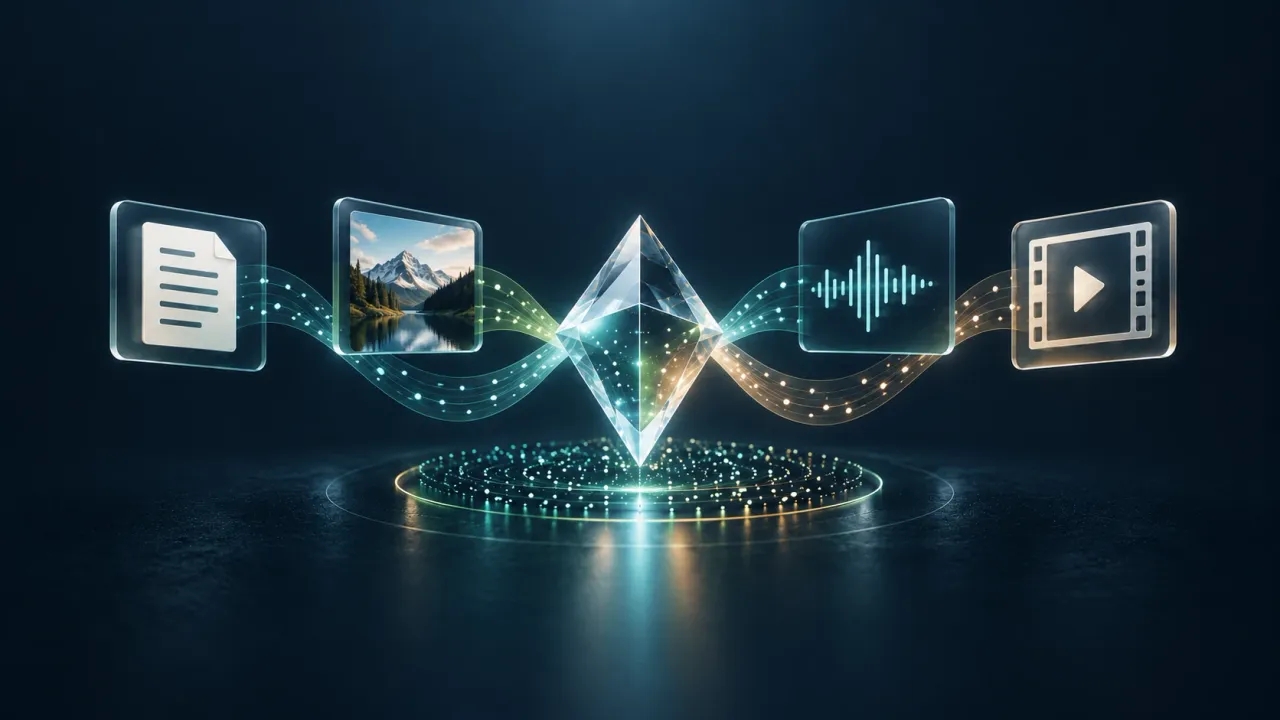
EmbeddingGemma 2 is already live in Flow-Like. Google’s new multimodal embedding model lets you build search across text, images, audio, and video in one shared space. Flow-Like runs the model locally and gives you workflow nodes for turning those inputs into searchable vectors.
Give your search more to work with
An embedding is a list of numbers that represents content in a form a search system can compare. Embed your source material, embed a question, and look for nearby vectors. That is the basis of semantic search: finding relevant content even when the wording differs.
EmbeddingGemma 2 extends that approach across media. A text query and an image can be represented in the same vector space, so a search can compare them. The model also accepts combinations of inputs, such as an image with accompanying text. Google’s EmbeddingGemma 2 model card describes the shared space and the model’s separate vision and audio encoders.
Consider a maintenance team. Its useful material includes a written procedure, a photo of an assembly, a technician’s recorded explanation, and a short repair clip. A search for replacing the inlet filter should have a chance to reach all of them.
That is a workflow you can build with EmbeddingGemma 2. Index the relevant items, compare a query against their embeddings, and return the original sources. Check the results against your own questions before putting them in front of the team.

This also changes what you can preserve during indexing. A transcript captures speech, but a repair demonstration contains visual information too. A photograph and its inspection note can carry meaning together. Joint inputs let you represent that combination as one searchable item.
Already inside the workflow
In Flow-Like, you load the model once and connect it to the embedding nodes your workflow needs. The embedding model guide covers the setup and supported inputs.
Embedding Model Info tells you what the loaded model supports, including input types, joint combinations, tasks, and output dimensions. It is a useful first connection because the installed encoders determine which media the model can process.
For mixed content, Embed Content produces one vector from an item’s ordered parts. Put a photo and its text description in the same item to encode them together. Embed Content Batch processes multiple items and returns one vector per item in the same order.
For files, Embed Audio and Embed Video accept a source file directly. Embed Video exposes Max Frames and Include Audio, so you decide how much of a clip to sample and whether its soundtrack belongs in the representation. Audio inclusion is off by default.
These nodes produce embeddings. Your workflow decides where to store them, how to search them, and what to do with the results.
Build a search you can inspect
Start with a small collection whose contents you know well. For the maintenance example, choose a procedure, a few photos, and short recordings about the same piece of equipment. That gives you a practical way to spot both useful matches and misses.
- Load the model. Use Flow-Like on a host with local ML execution. Supply the pinned EmbeddingGemma 2 example Bit to the Model Bit input of Load Embedding Model. A Bit describes a model and its assets. This example includes the backbone, vision and audio encoders, tokenizer, and configuration, with pinned download URLs and hashes. The full download is about 505 MB and works independently of the published model catalog.
- Prepare your source items. Extract text from documents and split long material into useful sections. For a recording or clip, connect the file to Source on Embed Audio or Embed Video, and the loaded model to Model. To combine audio or video with text, use Prepare Embedding Media with the matching Kind, add a text part to the prepared content, and pass the item to Embed Content.
- Create the index. Embed source items with Purpose set to
document. Store each vector alongside a reference to its source. For a document section or media segment, retain its location so a search result can take someone back to the relevant material. - Search with the same model. Embed the question with Purpose set to
query, using the same model configuration and output dimensions. Pass that vector to Vector Search against your stored collection, then return the matching source references.

Once retrieval works, you can add an answer model downstream. That is retrieval-augmented generation, or RAG: find relevant material first, then give it to a model as context for an answer. The retrieved media must be in a form that the answer model supports. Flow-Like’s RAG guide covers the broader pattern.
Search is valuable on its own, too. Sometimes the best result is the original diagram or the right repair clip, ready to open.
Local execution, with a boundary you control
Flow-Like’s EmbeddingGemma 2 integration runs through ONNX on a host with local ML support. Once the model assets are downloaded, the embedding step can run locally without sending the input to a hosted embedding API.
That gives you a concrete choice about where source material is processed. You still choose the storage and any downstream services. If you want the entire workflow to stay local, keep those steps local as well.
A few decisions that shape the results
Keep index and query compatible. Flow-Like returns vector-space identity, dimensions, metric, and a pipeline fingerprint with content embeddings. Preserve that metadata. Two vectors with the same number of values can still belong to incompatible spaces. When you change the embedding model or its configuration, plan to rebuild the index.
Choose dimensions by testing retrieval. Flow-Like supports 128, 256, 512, and 768 dimensions for this model. A 128-dimensional vector contains one sixth as many values as a 768-dimensional vector, but that does not mean identical search quality or a sixfold reduction in total database size. Start at 768, then compare smaller representations against questions that matter to your users. Google’s model card identifies 128 dimensions as best suited to text-only workloads.
Make each item worth retrieving. The model has an 8,192-token context limit, shared with the tokens used to represent media. Flow-Like rejects inputs that exceed the new adapter’s context. Split long documents and recordings into meaningful sections, and choose video sampling deliberately. A useful source segment is easier to evaluate and open than an entire archive compressed into one result.
Start with the files your search keeps missing
Pick a folder where useful knowledge already exists in several formats. Build a small index. Try questions whose answers you know, inspect the returned sources, and adjust the item boundaries or sampling where the results fall short.
A direct route to the right image, recording, or clip saves people from having to remember where it was filed.
EmbeddingGemma 2 is live in Flow-Like. Download Flow-Like, load the model, and give your search the rest of your knowledge base.
Get automation insights delivered
Sign up for our newsletter to receive the latest updates on Flow-Like, automation best practices, and industry insights. No spam — just valuable content.